AI Benchmark Leaderboard 2026: Latest Model Scores, Rankings & Results
AI Benchmark Leaderboard 2026: Who Is Really Winning the Race?
Ask five AI leaderboards which model is best today, and you may get three different answers. That is the real story of the best AI model in October 2026.
The top tier is crowded, the score gaps are small, and each ranking weighs different skills. Here is where things stand, why the tables disagree, and how to use them without being misled.
The Short Version
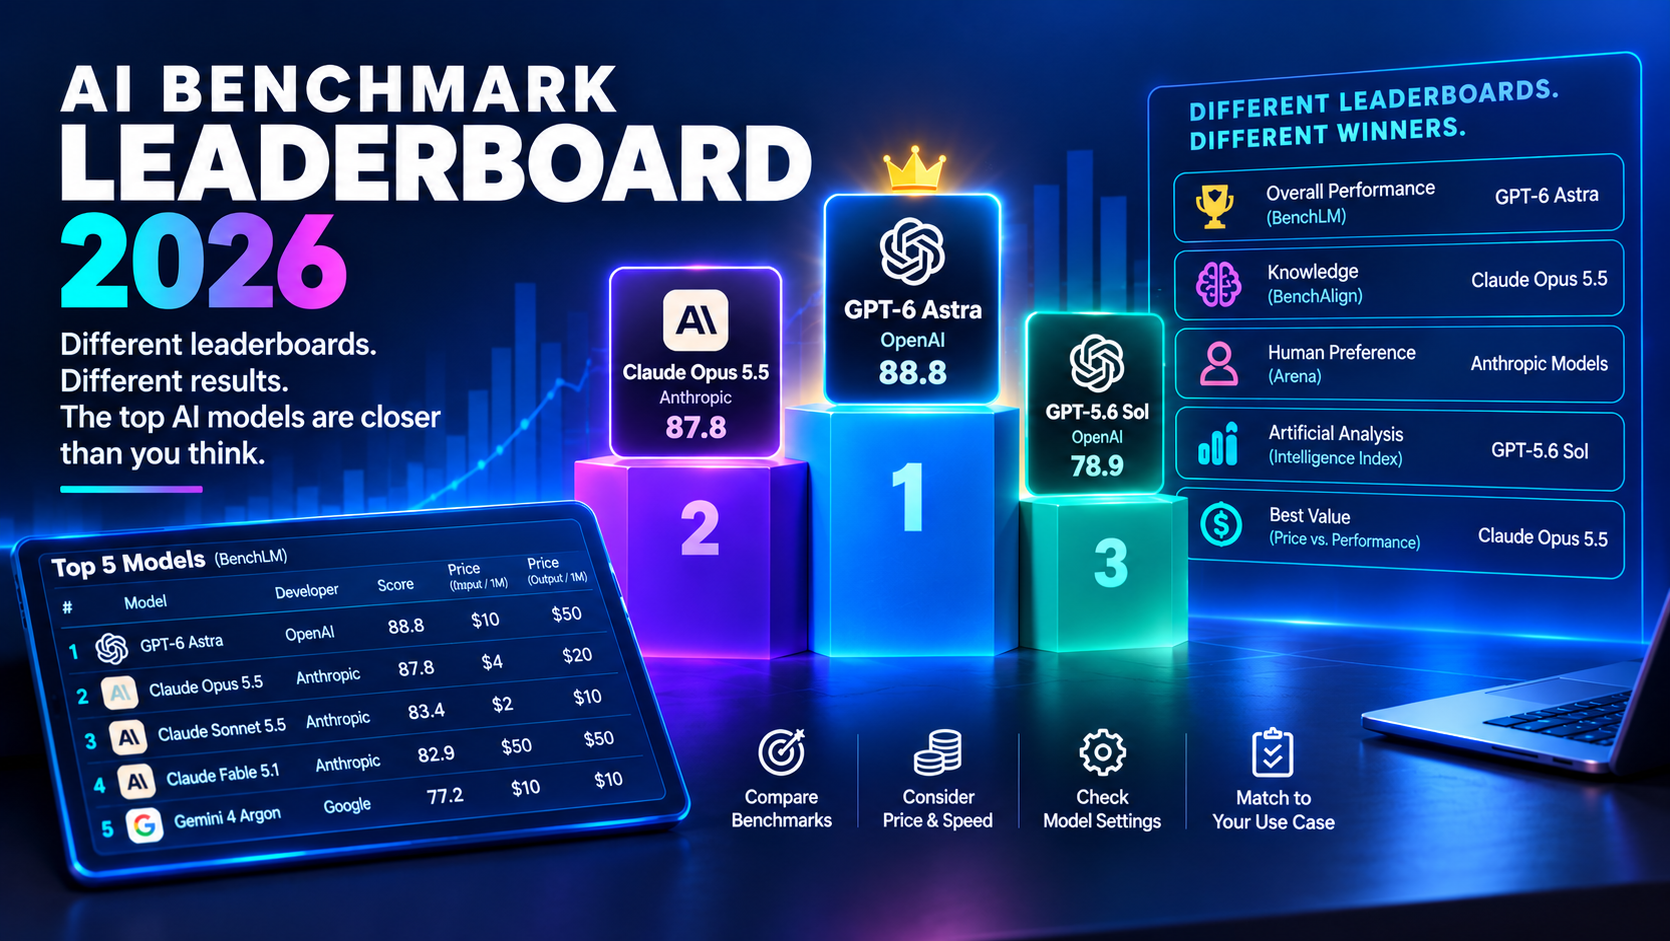
One aggregate leaderboard ranks GPT-6 Astra first overall, with Claude Opus 5.5 close behind.
The Artificial Analysis Intelligence Index, as compiled by one tracker, puts GPT-5.6 Sol on top.
On human-preference voting, Anthropic models held the top six Arena spots in late September.
Price differences between the leaders are large, and often matter more than a one-point score gap.
Overall Rankings: GPT-6 Astra Edges Ahead
On BenchLM's frontier table, GPT-6 Astra leads at 88.8, followed by Claude Opus 5.5 at 87.8 and Claude Sonnet 5.5 at 83.4. That tracker ranks 212 models, and its overall ranking was last updated on October 2, 2026.
The top ten, with evidence labels and output pricing as listed by BenchLM:
| Rank | Model | Developer | Score | Evidence | Output price / 1M tokens |
|
1 |
GPT-6 Astra |
OpenAI |
88.8 |
Supported |
$50 |
|
2 |
Claude Opus 5.5 |
Anthropic |
87.8 |
Estimated |
$20 |
|
3 |
Claude Sonnet 5.5 |
Anthropic |
83.4 |
Estimated |
$10 |
|
4 |
Claude Fable 5.1 |
Anthropic |
82.9 |
Supported |
$50 |
|
5 |
Claude Opus 5 |
Anthropic |
80.0 |
Supported |
$25 |
|
6 |
Claude Fable 5 |
Anthropic |
79.5 |
Supported |
$50 |
|
7 |
GPT-6 Sol |
OpenAI |
79.2 |
Estimated |
$10 |
|
8 |
GPT-5.6 Sol |
OpenAI |
78.9 |
Supported |
$20 |
|
9 |
GPT-6.1 Sol |
OpenAI |
77.6 |
Estimated |
$10 |
|
10 |
Gemini 4 Argon |
|
77.2 |
Estimated |
$10 |
Why the "Estimated" Label Matters
Half of the top ten carry only an "Estimated" tag, so those scores rest on thinner evidence. The tracker also warns that its score ranges don't establish how confident anyone can be in a given rank. In practice, the gap between first and second is small enough that a single new test could reorder them.
Artificial Analysis Index: A Different Order
The Artificial Analysis Intelligence Index is widely cited, and its leaderboard looks different. One aggregator reports that GPT-5.6 Sol leads at 58.9%, with Claude Opus 5.5 at 57.6% and Claude Sonnet 5.5 at 56.0%. It covers 215 models.
A separate daily tracker, refreshed on October 3, lists Claude Opus 5.5 at its maximum setting as the top model, with a score of 57.6. The two lists agree on Opus 5.5's number but differ on who is first. The likely reasons are which model variants and settings each site includes, and how often each refreshes.
Knowledge Tests: Anthropic Takes the Lead
On factual knowledge, the order flips again. Claude Opus 5.5 leads the BenchAlign knowledge ranking at 88.3, ahead of GPT-6 Astra at 85.8 and Claude Fable 5.1 at 85.0. For teams building research tools, internal assistants, or document-heavy products, this category may be more relevant than the overall score.
Human Preference: The Arena Picture
Not every ranking uses fixed tests. Arena (formerly LMArena and Chatbot Arena) relies on blind head-to-head votes from users. The platform completed its rebrand to "Arena" on January 28, 2026.
A prediction-market page tracking the board reported that, as of September 25, Anthropic held ranks one through six, with claude-opus-5.5-high at 1509. The same page noted that Gemini 4 Pro is widely reported to be targeting an October launch, though Google hasn't announced a date. That is a market page, not an official source, so treat it as a snapshot and check the live Arena leaderboard.
Earlier in the year, claude-fable-5 topped the text board at 1510 in a June snapshot. Anthropic's lead on this vote-based board has held through several model releases.
Price and Speed: The Hidden Variables
A high score means little if the bill is unaffordable. Based on BenchLM's listings, GPT-6 Astra costs $10 input and $50 output per million tokens, Claude Opus 5.5 costs $4 and $20, and Claude Sonnet 5.5 costs $2 and $10.
| Model | Input / 1M | Output / 1M | Overall score |
|
GPT-6 Astra |
$10 |
$50 |
88.8 |
|
Claude Opus 5.5 |
$4 |
$20 |
87.8 |
|
Claude Sonnet 5.5 |
$2 |
$10 |
83.4 |
Opus 5.5 is within a point of the leader at well under half the price. Sonnet 5.5 sits at roughly a fifth of Astra's price, with about a five-point gap in score. For high-volume work, that trade-off often decides the choice.
Open-Weight Models: Closing In
Open-weight AI models, which developers can run themselves, are still behind the closed leaders. BenchLM lists MiMo-V2.6-Pro as the best open-weight model, at #11 overall. Moonshot's Kimi K3 sits at #15 with a score of 72.14.
For companies that need data control or self-hosting, the gap to the top is real but narrowing.
How to Read a Leaderboard Without Being Fooled
1. Check who ran the test: Vendor-reported scores and independent runs can differ.
2. Look at the evidence label: "Estimated" is weaker than "Supported."
3. Compare settings: The same model can score differently at "high" and "max" reasoning.
4. Match the benchmark to your task: Coding, knowledge, and chat quality are separate skills.
5. Cost factor: A near-tie in score is not a tie in price.
Arena-style voting has its own limits. Critics have raised concerns about how such boards can be gamed, and one explainer notes that the board separates very close champions rather than good models from bad ones.
Why This Matters
AI model choice now affects real budgets, products, and hiring. The leaderboards show a field where the top few models are nearly interchangeable on headline scores, and the differences show up in price, speed, and specific skills. Anyone picking a model should test it on their own tasks, since a ranking can't do that for them.
Expect more movement soon. A Gemini 4 Arena launch, if it comes, could shake up the human-preference rankings.
Conclusion
October 2026 gives no single champion. GPT-6 Astra leads one aggregate, Claude Opus 5.5 leads on knowledge and human voting, and GPT-5.6 Sol tops one version of the Artificial Analysis table. The practical lesson is to read the methodology behind each number, weigh price alongside performance, and re-check often, because these rankings change quickly.
Frequently Asked Questions
Which AI model is number one on the leaderboard right now?
It depends on the ranking. BenchLM's overall table places GPT-6 Astra first at 88.8, while Claude Opus 5.5 leads on knowledge and tops one daily tracker. Always check which leaderboard and settings you are looking at.
Why do different AI leaderboards show different winners?
They measure different things. Some use fixed benchmark tests, others use human votes, and each handles model settings, estimates, and updates differently. Small score gaps can easily flip the order.
What is the best AI model for the money?
Claude Opus 5.5 and Claude Sonnet 5.5 score close to the leader at much lower listed prices than GPT-6 Astra. The best value depends on how much output your project generates and how much accuracy you need.
What is the best open-source AI model in 2026?
BenchLM lists MiMo-V2.6-Pro as its top open-weight model, ranked #11 overall. Kimi K3 is also a strong open-weight option at #15.
Is Gemini 4 Argon among the top AI models?
It ranks #10 on BenchLM's frontier table with a score of 77.2 labeled "Estimated." A possible Gemini 4 Pro release could change Google's standing, though no date has been announced.
Stay ahead: Visit Trendzyvibe for the latest breaking news, trending stories, and in-depth updates on AI, technology, and more. Bookmark us so you never miss the next ranking shake-up.
Leave a Reply
Your email address will not be published. Required fields are marked *